AI video prompts, with the results
Each prompt sits under its clip. Three misses sit next to follow-up attempts: garbled signs, a fold that made no sense, and a city hanging upside down. The paper rewrite simplifies the task rather than making the requested bookmark.
- 7 prompts, 7 clips
- 3 failures shown
- Copy any prompt
Three failures and their rewrites
Each pair is the same idea prompted twice. The first clip of a pair is the first result; the second is the first result of the rewritten prompt.
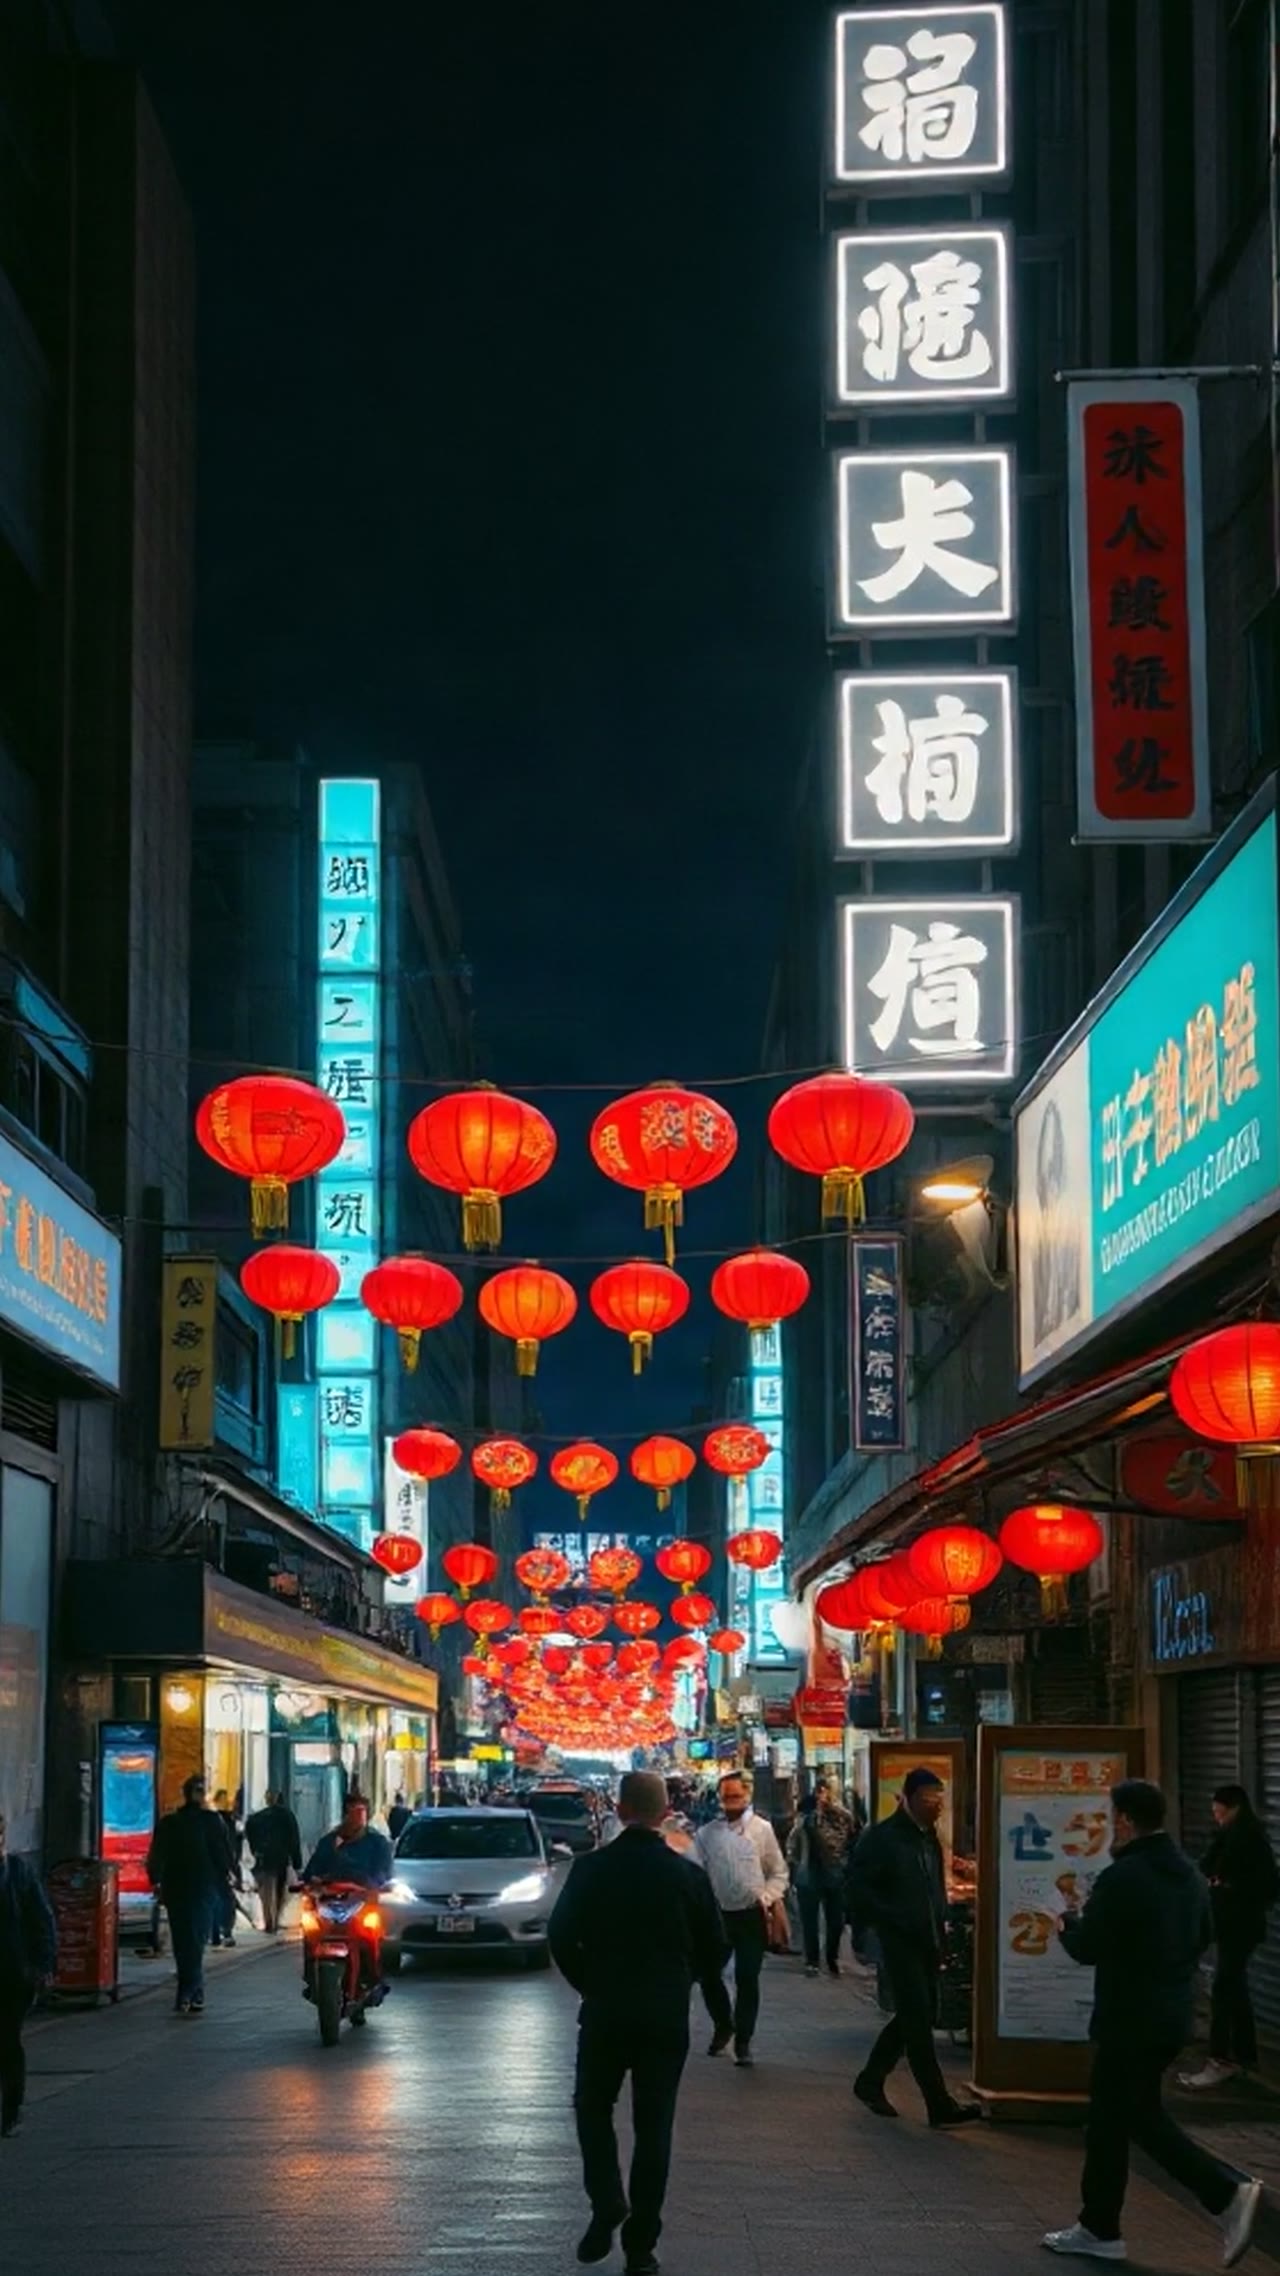
Miss: "no text" still gave signs
The prompt ended with "no on-screen text, no logos". The shop signs are full of lettering that is not any language.
Prompt
Vertical street scene. A quiet rain-wet city street at dusk, neon reflections in the puddles, a cyclist in a yellow raincoat rides through the frame from left to right. Handheld feel, cinematic colour. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Fix: describe a street with no shops
The rewrite describes brick walls, closed shutters and street lamps, so there is nothing to put a sign on. No lettering anywhere. The cyclist crosses the street rather than riding along it.
Prompt
Vertical street scene. A quiet rain-wet residential street at dusk between plain brick walls and closed grey shutters, lit only by warm street lamps reflected in the puddles. A cyclist in a yellow raincoat rides through the frame from left to right. Handheld feel. There are no shops, no signs, no neon and no lettering anywhere in the scene.
Vivix W1 fast · 5 s · 720×1264
Miss: a task with many steps
Asked to fold paper into a corner bookmark. The hands and paper look natural, but the folds follow no logic and the result is not a bookmark.
Prompt
Vertical top-down view. Two hands fold a sheet of blue paper into a corner bookmark on a wooden desk. Locked camera, natural daylight, every fold clearly visible. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Simpler task: one fold
The rewrite asks for a single fold, corner to corner, then hands at rest. It made the triangle and pressed the crease, but did not attempt the original bookmark. The sheet is not an exact square.
Prompt
Vertical top-down view, locked camera, natural daylight. Two hands take a square sheet of blue paper on a wooden desk and make one single fold: corner to opposite corner, so the square becomes a triangle. The hands press the crease flat and then rest beside the triangle. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Miss: composition left open
Asked for a skyline time-lapse in a vertical frame. The model filled the empty upper half with a second city hanging upside down.
Prompt
Vertical b-roll. Time-lapse of a city skyline at dusk as the building lights come on and clouds drift, locked-off camera. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Fix: say what fills each part of the frame
The rewrite puts the skyline in the lower third and says the upper two thirds are open sky and nothing else. Upright city, drifting clouds, windows lighting up.
Prompt
Vertical b-roll, locked-off camera on a riverbank. A city skyline stands upright along the horizon in the lower third of the frame; the upper two thirds are open dusk sky with slow drifting clouds and nothing else. Windows light up one by one as the sky darkens. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Recorded on 10–11 November 2026 with Vivix W1 fast through its API, at 9:16 and 720×1264. Each clip is the first result of its prompt. They are shown without sound. ClipScript does not sell this model; the people and objects in the clips are generated, not real.
What makes an AI video prompt work?
These runs suggest ideas to try, not rules proven across prompts. A single fold was simpler than the bookmark task, although it did not make a bookmark. A street of brick walls and closed shutters produced no visible signs in the second clip. A prompt placing the skyline in the lower third produced an upright city in its second clip. Each comparison also changed the requested scene, so it does not isolate one cause.
- Clips on this page
- 7, from 7 prompts
- Failed first time
- 3
- Follow-up attempts
- 3; one simplified the task
One that worked first time
For comparison: a prompt with one subject, one action and its light already stated.
Honey on pancakes
Subject, action, light and speed are each one phrase, and each came through. About two seconds in, the honey gathers into a lump before it spreads.
Prompt
Vertical macro food shot. Honey drizzles slowly onto a stack of three pancakes, a little steam rising, warm morning light, slow motion. No on-screen text, no logos, no watermark.
Vivix W1 fast · 5 s · 720×1264
Recorded on 10–11 November 2026 with Vivix W1 fast through its API, at 9:16 and 720×1264. Each clip is the first result of its prompt. They are shown without sound. ClipScript does not sell this model; the people and objects in the clips are generated, not real.
A structure to write prompts in
Shot
The framing and the camera: "vertical close-up from above, locked camera". Say "locked camera" when you want no movement.
Subject and the one action
Who or what, and the single thing it does. If you wrote "then", consider a second clip.
Place and light
Describe the setting in positive terms, including the things that make unwanted details impossible.
Frame split
For vertical clips, say what occupies the top and the bottom.
What these runs do not show
One model
Every clip here is Vivix W1 fast. Other models fail in other places; the three rules are habits, not laws.
One try each
A prompt that failed once might pass on a second try. These are first results, not repeated trials or controlled comparisons.
Short clips
All are 5 seconds. Longer clips give a model more time to drift.
AI video prompt questions
Why did "no text" fail here?
In our first run the model still drew signs on a street of shops. A different street description produced no visible lettering in the follow-up; that single pair does not establish why.
How long should a prompt be?
The prompts here run from roughly 30 to 60 words. We did not test prompt length systematically.
Should I write camera terms?
In the examples shown, the model followed some requested framing and movement. Other camera moves and repeated trials were not tested.
Can I generate clips from these prompts on ClipScript?
No. The clips on this page were recorded with Vivix W1 fast, a model ClipScript does not sell. What ClipScript does for this format: the TikTok transcript of a video you are studying, and a free voiceover script from your topic on the TikTok script generator.
More tools
Explore each tool’s instructions, output limits and available recorded examples.